Informal Verification
Against impossible odds, formal verification is both cool and practical now. However, verification is first and foremost an exercise in building trust, for which a formal approach may be sufficient but not necessary. We explore the use of System One models as informal proof checkers, and argue that informal methods can play a complementary role in establishing trust in agentic software engineering workflows.
Letting agents make changes to a complex system requires trust.
Trust can be built empirically: how often do you need to correct an agent? How frequently did it break production? But a track record alone is not enough. You can see bugs getting closed fully autonomously week after week, and yet not be able to distinguish a mounting pile of tech debt from surgical fixes rooted in a deep understanding of the system and its users. Worse, an agent might write flawless clean code wherever you look, yet explain its work in such roundabout ways that you don’t feel comfortable enough to let it loose.
The missing piece is epistemic trust: you need to believe that the resulting system works the way that you think it does, that it is aligned with your mental model. From observing the example below, you would assume that the machine sorts marbles by colour. Peeking inside, you discover a mechanism that sorts by size instead, which just happens to be equivalent under normal operation. Feeding an abnormal input, a large blue marble, confirms the misalignment.
A broken clock is never right in a high-dimensional space
Building empirical trust is the domain of testing: we observe how the system actually behaves.
Building epistemic trust requires arguing why the system behaves correctly, why it is aligned. This is an iterative affair where silent assumptions are revealed, and where non-obvious leaps of reasoning are broken down into smaller steps. Through this process, the low-dimensional state of (dis-)agreement is exploded into a high-dimensional space of assumptions, conclusions, and the rich geometry between them. Agreement along so many different dimensions is a very strong signal in favour of true alignment. Formal and informal arguments can both serve this purpose.
Agents with access to a formal proof assistant like Lean are able to formalize some arguments in a way that can be checked by a deterministic kernel. The chance of the kernel accepting a flawed argument (or rejecting a correct one for that matter) is not zero, but reasonably small. And once accepted, the kernel won’t suddenly change its mind.
And yet, a formal approach cannot provide absolute trust either, due to errors, ambiguities, or simply drift in the formalization itself. In the words of Alan Perlis, “one can’t proceed from the informal to the formal by formal means.” For example, such questions arose in 2025 about which statement the AI-generated Lean proof of Erdős problem #124 had actually established, and have also been studied in the context of formally verified distributed systems.
“It is worth noting that of the 290 OpenAI theorems which come with Lean code, around 38 of them have the property that the Lean code does not even state, let alone prove, the main theorem of the paper.”
An informal argument, on the other hand, can significantly reduce the translation risk or work even in cases where formalization is impractical in the first place. For example, how do you prove that your software uses a third-party API correctly, or that the rendering of a website matches its CSS rules? In exchange, an informal approach accepts a higher error rate when checking the proof — either due to ambiguities in the prose or laziness on the part of the reviewer.
Formal and informal proof can be complementary verification tools for building epistemic trust.
System One models are informal proof checkers
If we’re hoping to incorporate informal arguments into frenetic agentic software engineering workflows, we need a way to produce them at scale. We need to provide our agents with the informal equivalent of Lean, so that they can do all of the heavy lifting and get their work checked automatically.
What do we want out of an informal proof checker?
- Accept obviously true reasoning steps.
- Reject obviously false reasoning steps.
- Reject imprecise and ambiguous steps.
- Reject big leaps in reasoning, even if correct, to force the proof author to break down their argument into smaller steps.1
System One models like Jev are informal proof checkers.
The next example causes even a model like Fable 5.2 to reason for about a minute before it can answer the question, which puts it firmly in the non-obvious category. Jev’s response splits almost evenly between true and false, indicating that it cannot decide confidently in either direction.
When a frontier agent is tasked with getting Jev to accept this conclusion, it is forced to decompose the conclusions it arrived at through its internal reasoning chain2, resulting in a large tree of sub-claims like the following:
Used this way, Jev effectively accepts any deductive step that a capable LLM can follow intuitively, meaning without the use of internal reasoning tokens. This strikes the necessary balance between following informal reasoning at all (which takes a strong world model and plenty of common sense) and forcing the proof author to spell things out at a higher level of detail.
Input assumptions and claims are written in natural language, making it easy for a human observer to verify them and follow the reasoning to any level of detail. And of course there is no formalization step, avoiding the problem of formally proving the wrong theorem.
And Jev is multimodal, so we can also reference diagrams in our argument:
The cost and latency of running a System One model in the agent loop are negligible relative to the cost of the agent itself and the latency of other tool calls.
But as expected, there is a price to pay. The world model and common sense that let Jev follow informal deductions make it susceptible to errors a human reviewer might make as well.
First, like any System One model, Jev is not perfectly deterministic, so reasoning steps that fall right around the confidence bar separating “true” from “false” can end up flip-flopping.
A more interesting failure mode is caused by Jev’s ability to resolve some cases of ambiguity the way a fluent human reader does whenever one reading is dominant. Given “the controller passes the invoice to the serializer after it validates it”, it is 95% confident that the controller does the validating, even though the sentence admits another reading. A step can therefore pass under an interpretation the author did not intend.
Like a human, Jev has knowledge about the world, and thus can silently fill in facts it considers too obvious to state explicitly. This ability is what makes informal reasoning possible in the first place, but the bar can be different for different audiences.
Tooling and prompt engineering can mitigate some of these issues, but ultimately this is the explicit trade we are making: System One models allow us to scale human-like informal reasoning — warts and all.
The beatings will continue until trust is built
Claims in day-to-day software engineering look less tidy. Here is one (purely for illustration) that an agent might make while reviewing a new endpoint in a multi-tenant application:
GET /invoices/:idnever returns another tenant’s invoice.
Proving this formally would mean modelling the web framework, the ORM, and the database. An informal proof can start from premises either grounded directly in the code or at least supported by documentation:
- P1. Every request to
/invoicespasses throughTenantMiddleware, which setsCurrent.tenant_idfrom the session. (app/middleware/tenant_middleware.rb) - P2.
Invoicedeclares a default scope ofwhere(tenant_id: Current.tenant_id). (app/models/invoice.rb) - P3. Queries built through a model include that model’s default scope. (Rails API documentation)
- P4.
InvoicesController#showloads the invoice withInvoice.find_for_display(params[:id]). (app/controllers/invoices_controller.rb)
The checker judges every premise in the context of its cited witnesses. From there, the argument might proceed in small steps, each of which the checker again either accepts or rejects:
- S1. By P1,
Current.tenant_idis the requesting tenant for the duration of#show. ✓ - S2. By P2 and P3, every query built through
Invoicereturns only rows that belong to the current tenant. ✓ - S3. By P4 and S2, the invoice loaded in
#showbelongs to the current tenant. ✗
Here the checker happens to reject S3. P4 tells us that find_for_display loads the
invoice, but nothing in the premises says how. In particular, nothing says that it builds
its query through Invoice’s default scope. Following that thread to the method’s
definition turns up the problem:
def self.find_for_display(id)
  find_by_sql([<<~SQL, id]).first
    SELECT invoices.*, customers.name AS customer_name
    FROM invoices JOIN customers ON customers.id = invoices.customer_id
    WHERE invoices.id = ?
  SQL
end
find_by_sql runs the query as written, default scope or not. Any tenant can read any
invoice by guessing its id.
Note what the checker did not need to do. It didn’t need to know the semantics of
find_by_sql, and it didn’t go searching the codebase. It simply refused a step whose
conclusion doesn’t obviously follow from the premises.
The point here is not that the agent could not possibly have found this issue unaided. But instead of a single agentic thumbs-up at the end, a human following the work has seven concrete claims (four premises and three reasoning steps) to match against their own mental model. And the resulting proof can serve as a durable artifact that can be cheaply re-checked against future revisions without an agent in the loop.
autoground — an informal proof assistant
Work is needed to turn these ideas into a useful tool. autoground is an attempt at doing so, focusing on grounded agentic explanations as a first use case. It includes a lightly structured language called brief for writing informal proofs, and a Jev-based utility for checking them.
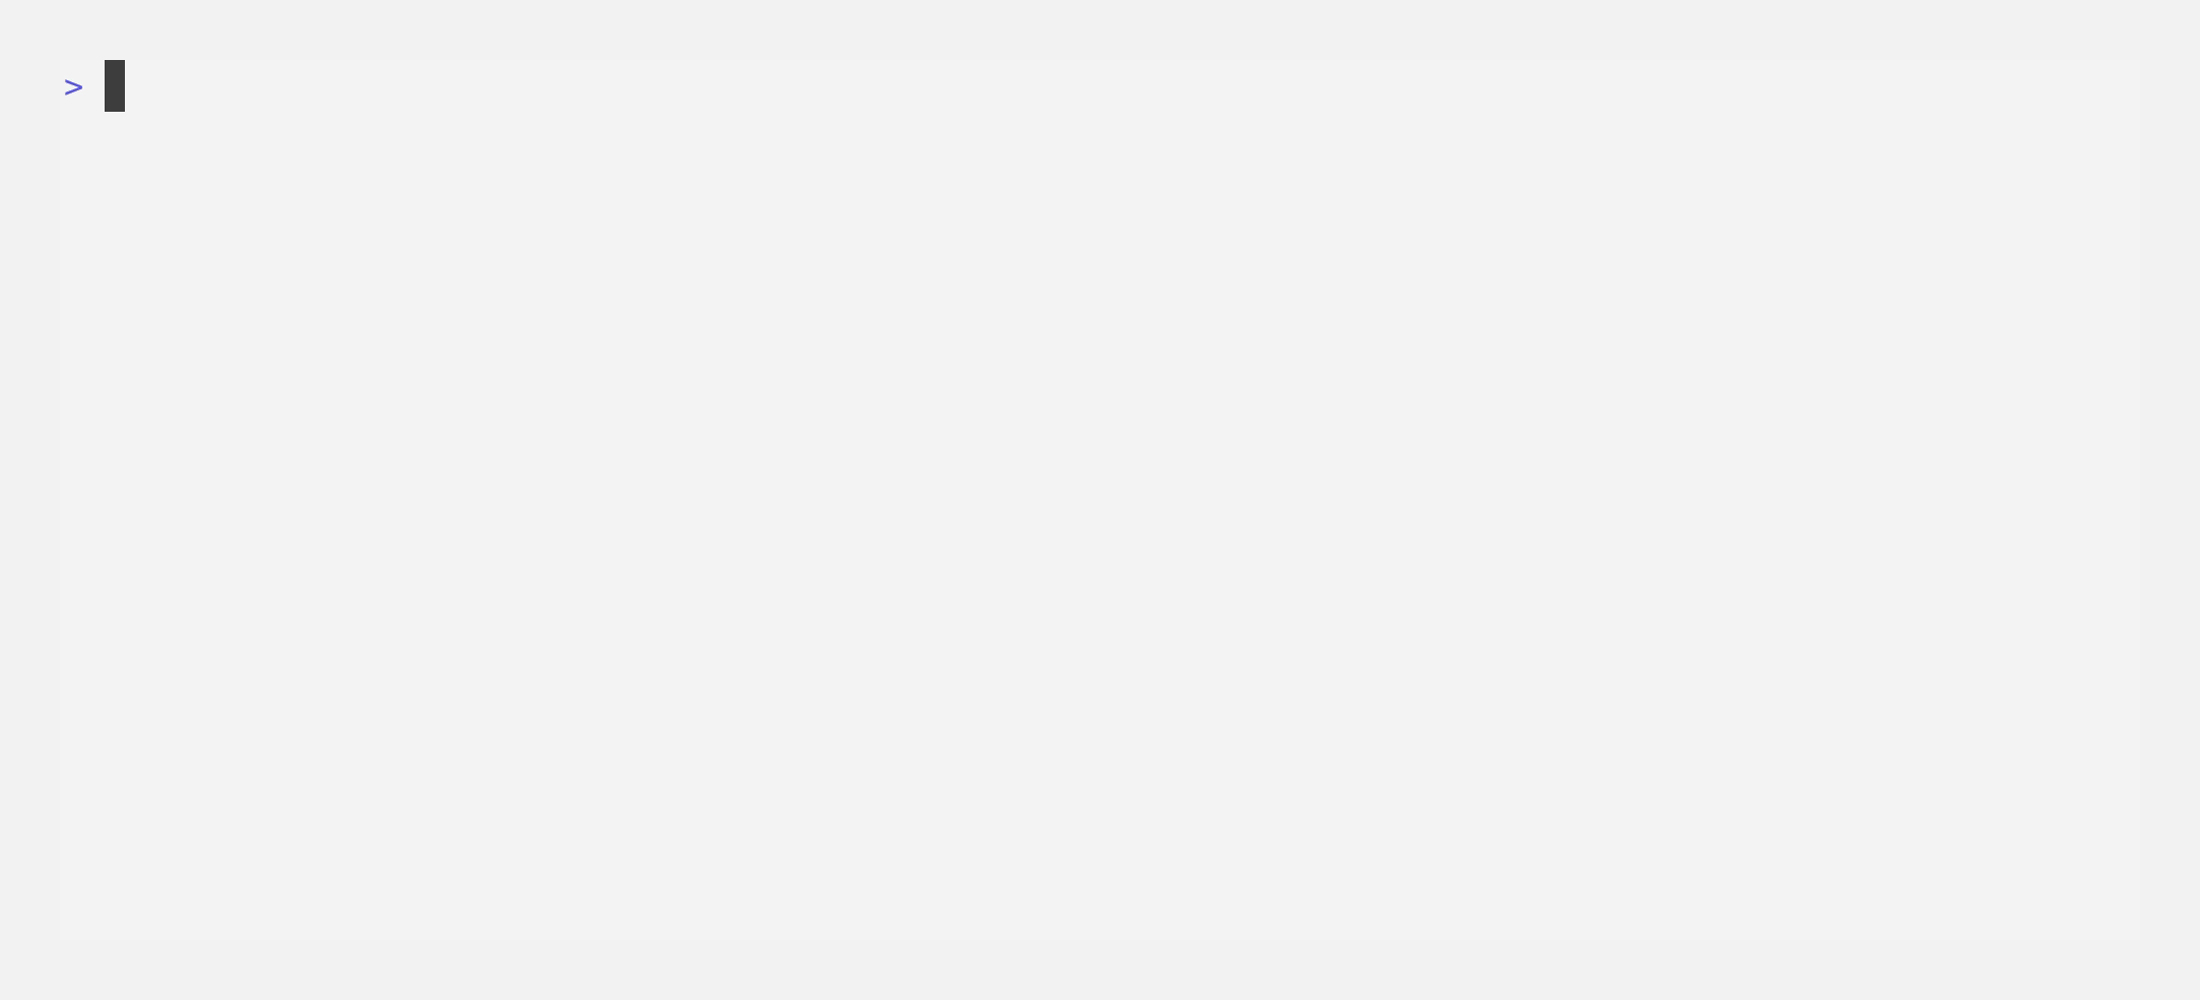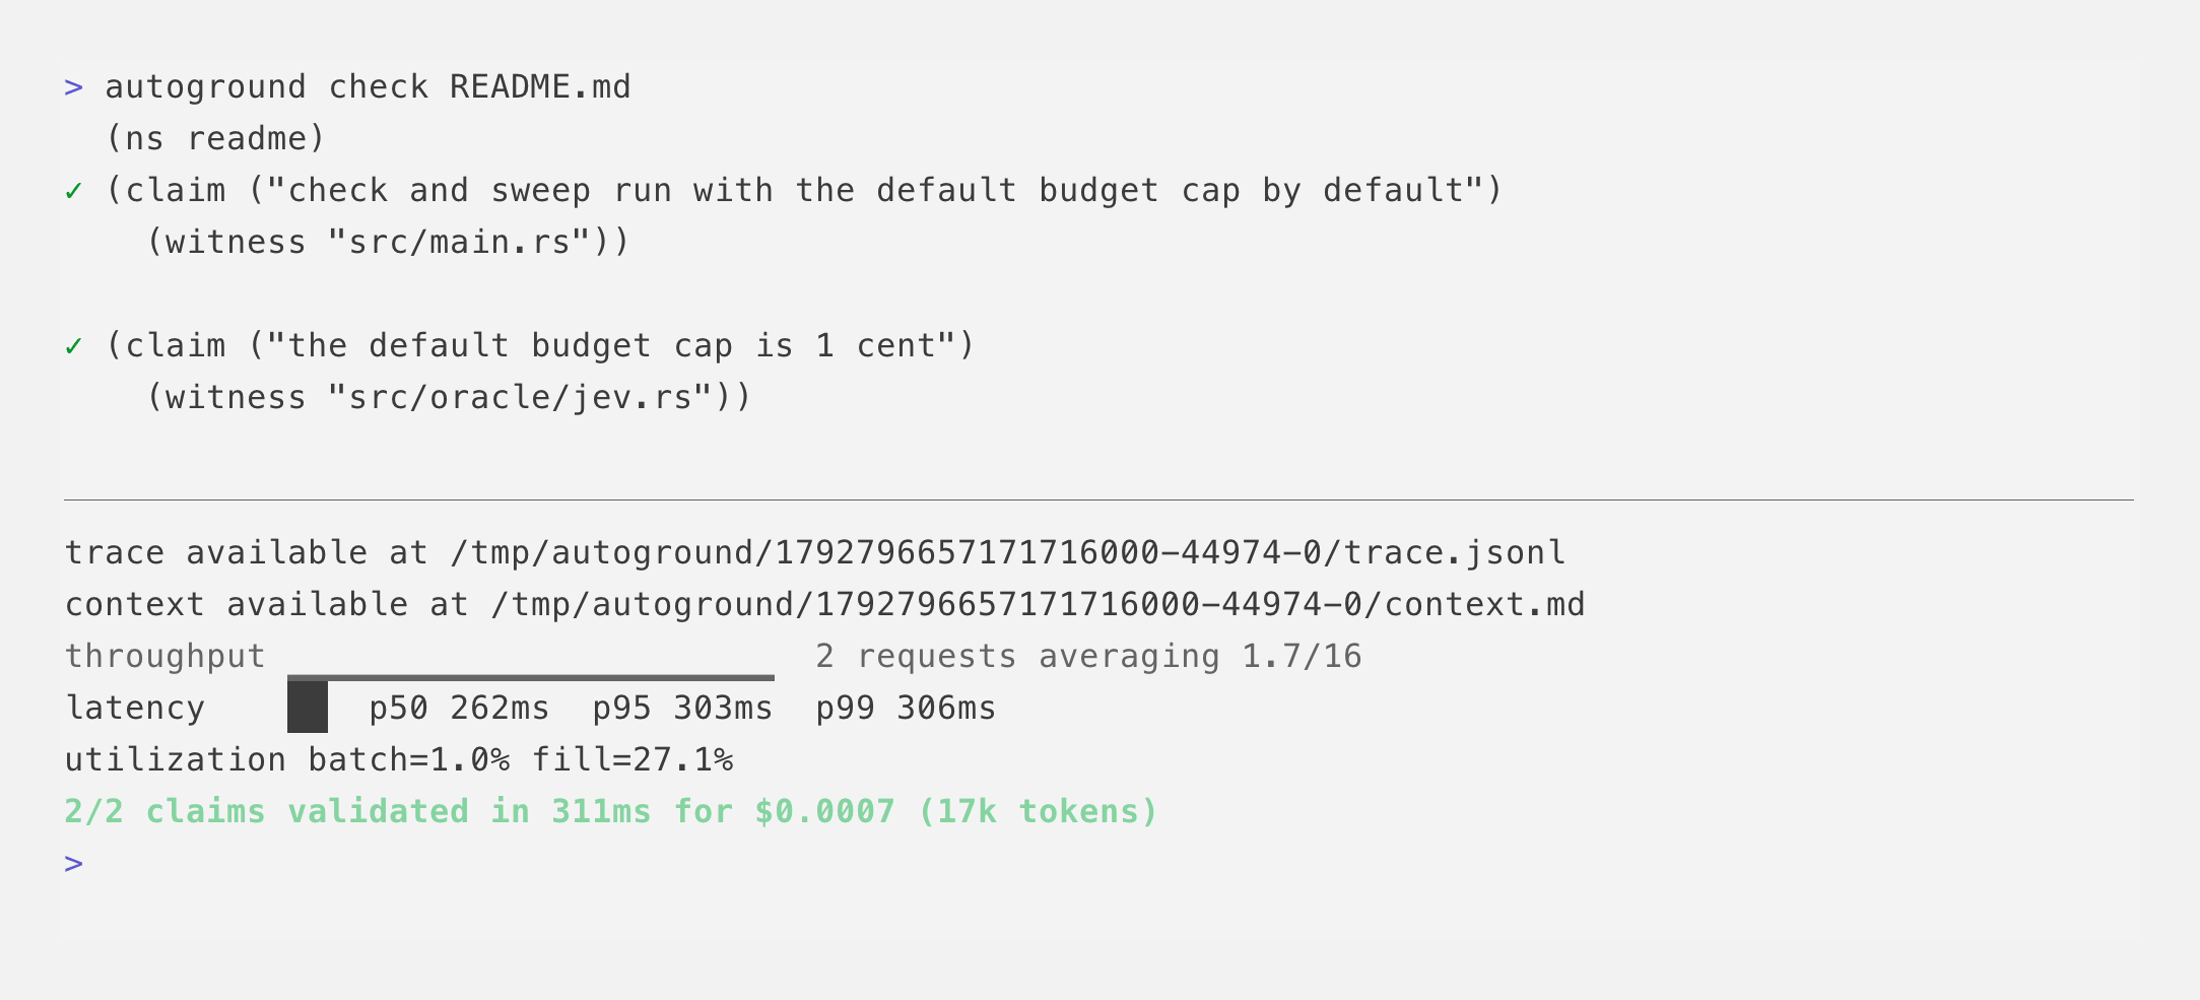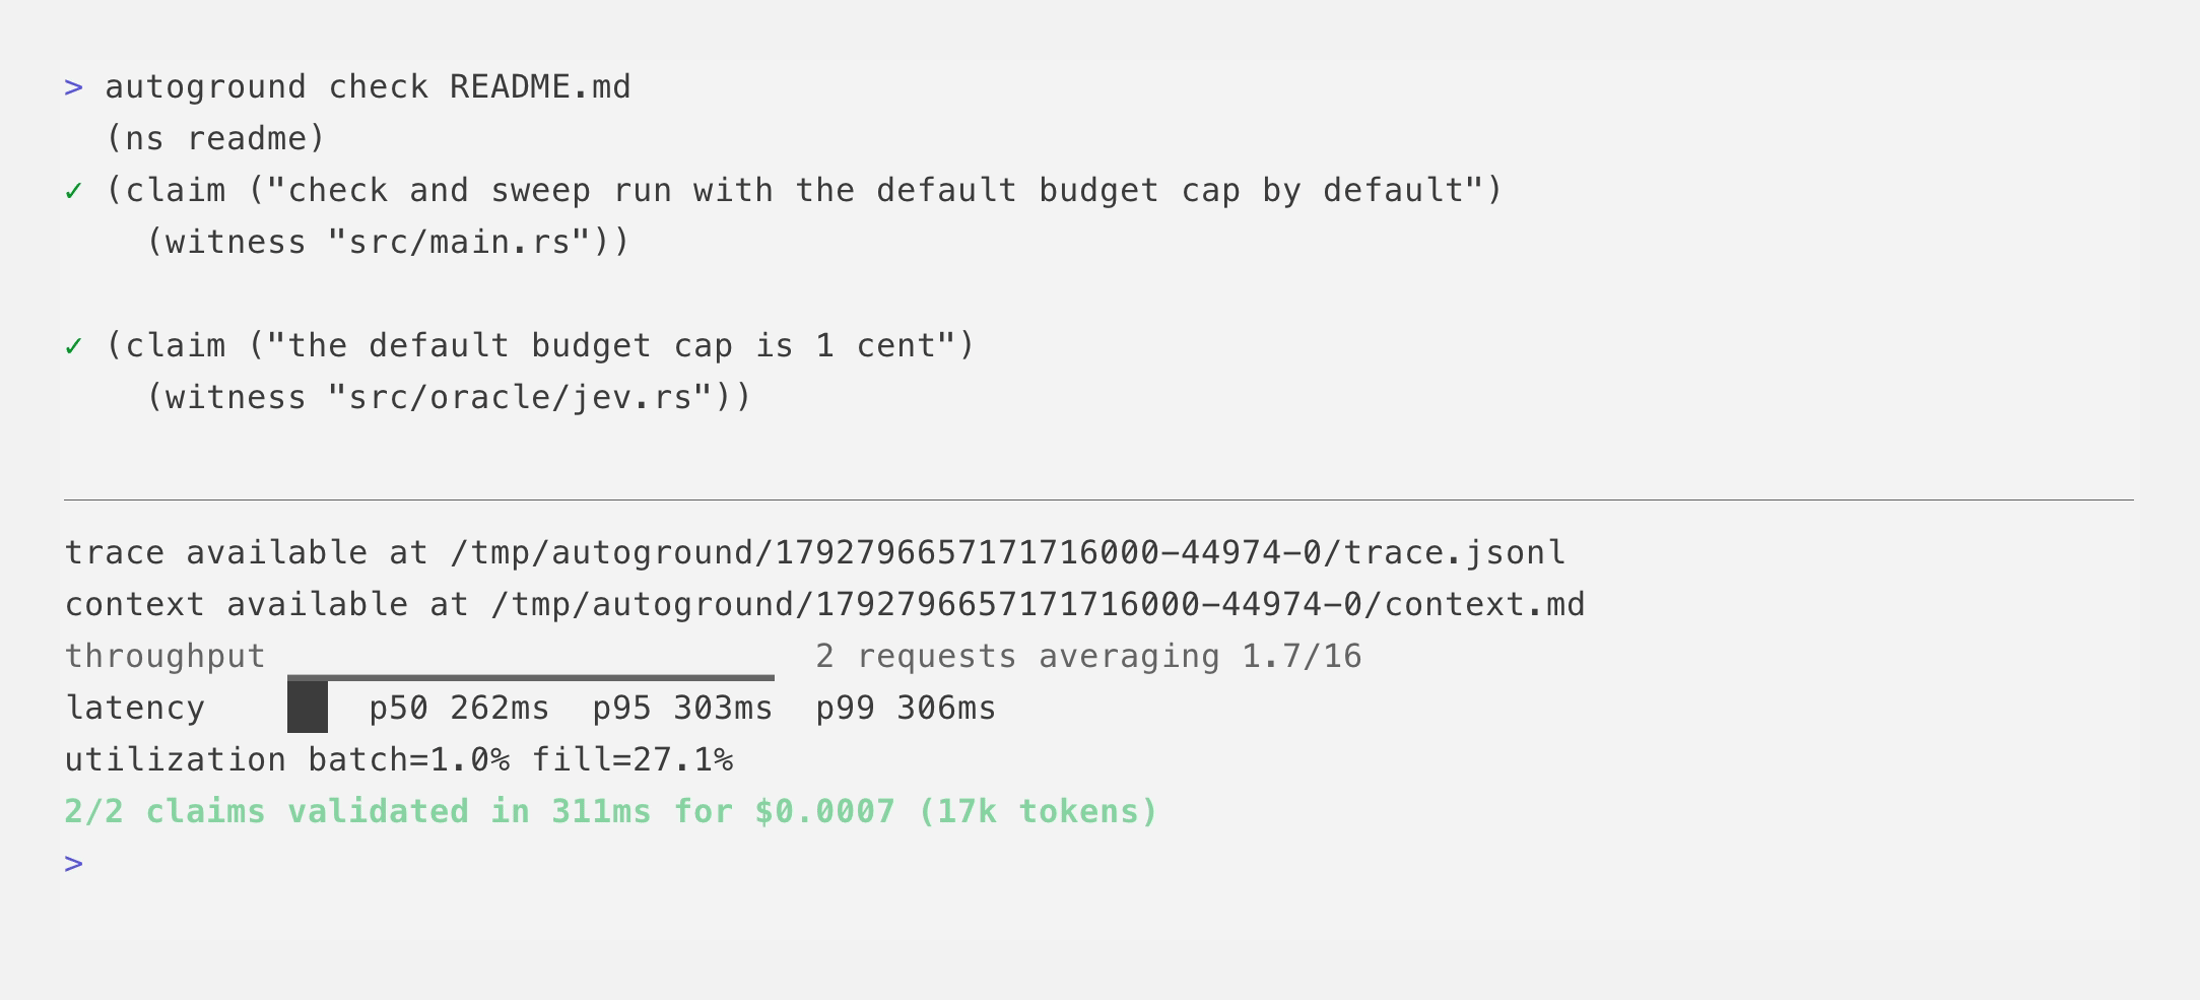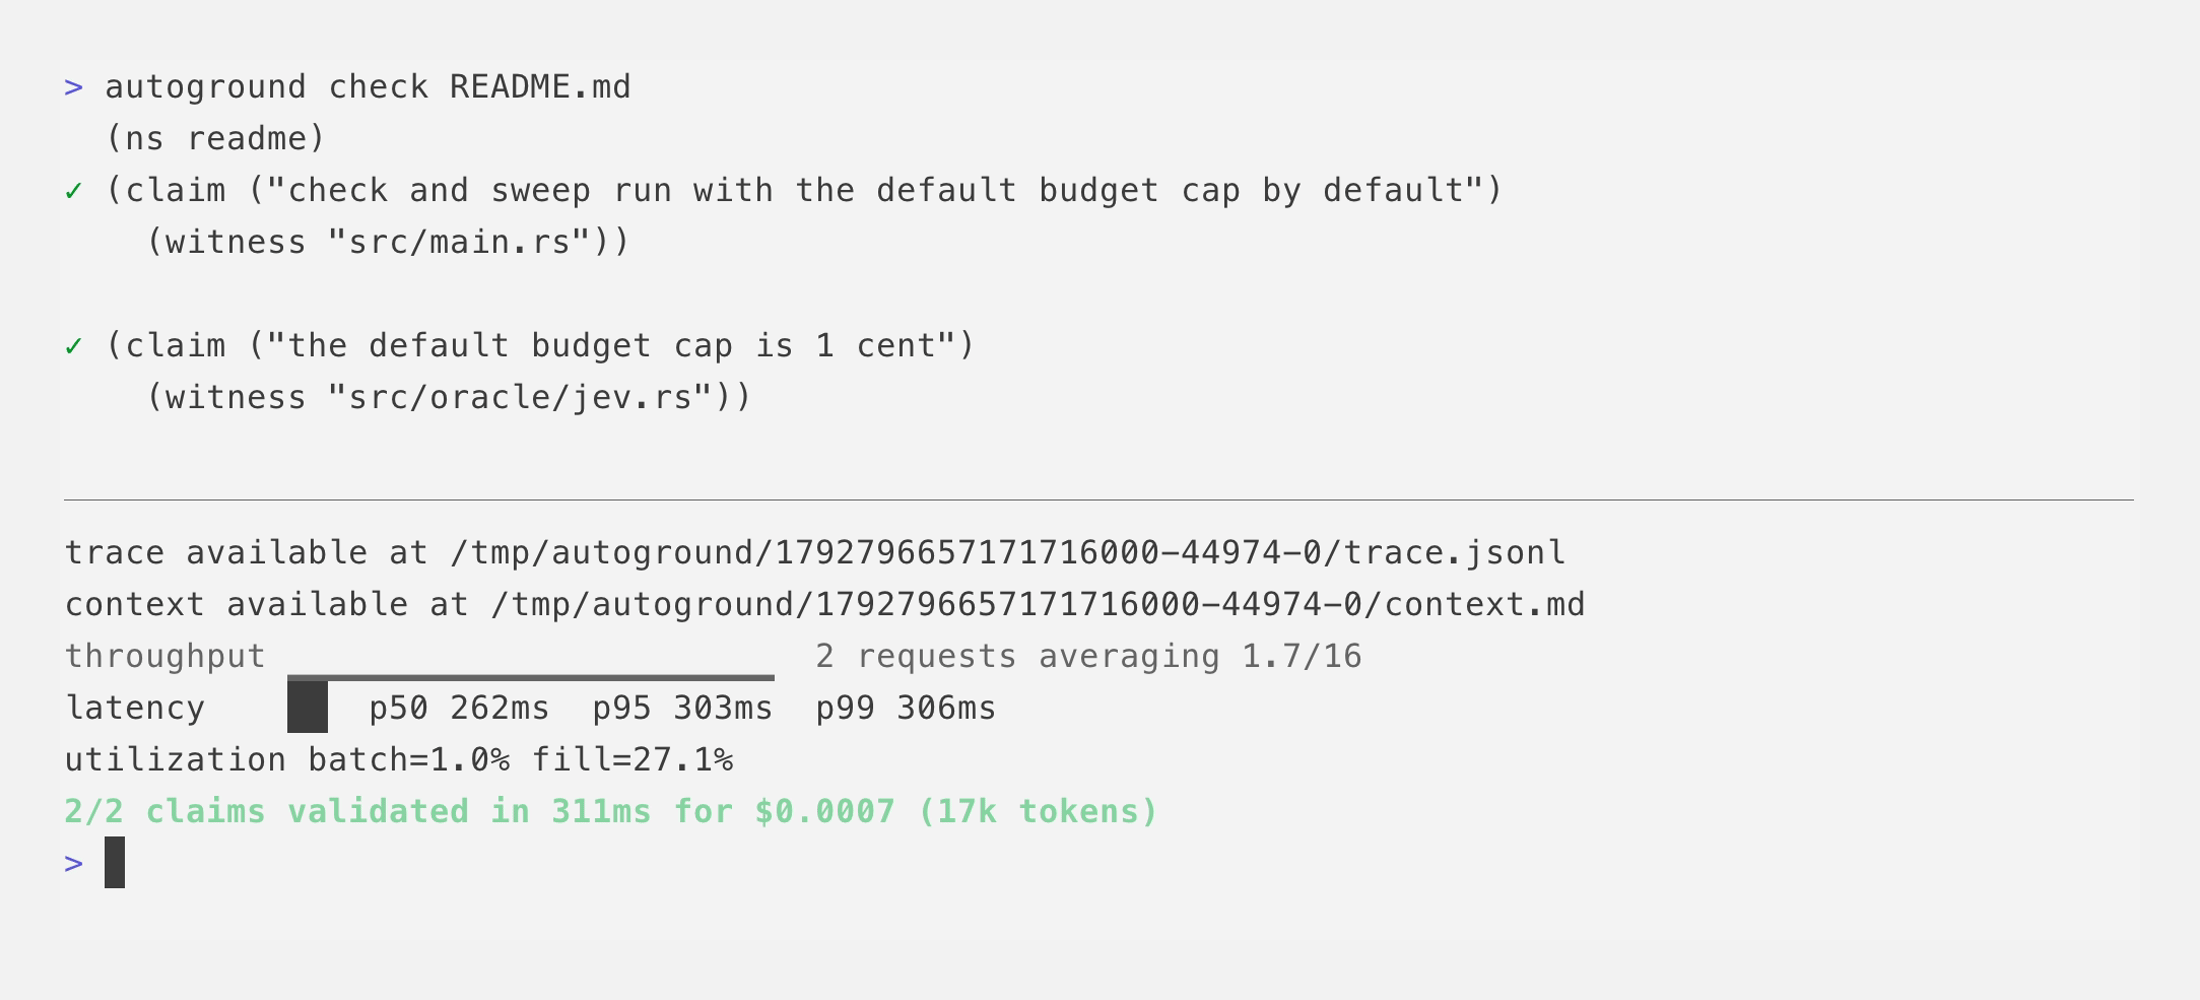
The brief language tries to encourage consistent terminology and gradual decomposition of complicated arguments into atomic claims connected by deterministic logic operators — both of which take aim at the failure modes above. Precise terms leave less room for a knowledgeable reader’s guess, and small claims composed in a deterministic way keep Jev focused.
None of this turns an informal proof into a guarantee. But proofs are about more than guarantees: we seek proof for the understanding gained and the trust built along the way3. When a specification is hard to come by, informal verification can still provide both.
-
This requirement has precedent in formal proof assistants. The Mizar checker deliberately accepts only “obvious inferences”, forcing authors to decompose anything larger. ↩
-
This is somewhat analogous to Codemode, where agents lift control flow out of their own reasoning and into deterministic code. ↩
-
See also Proofs and Refutations, by Imre Lakatos ↩